
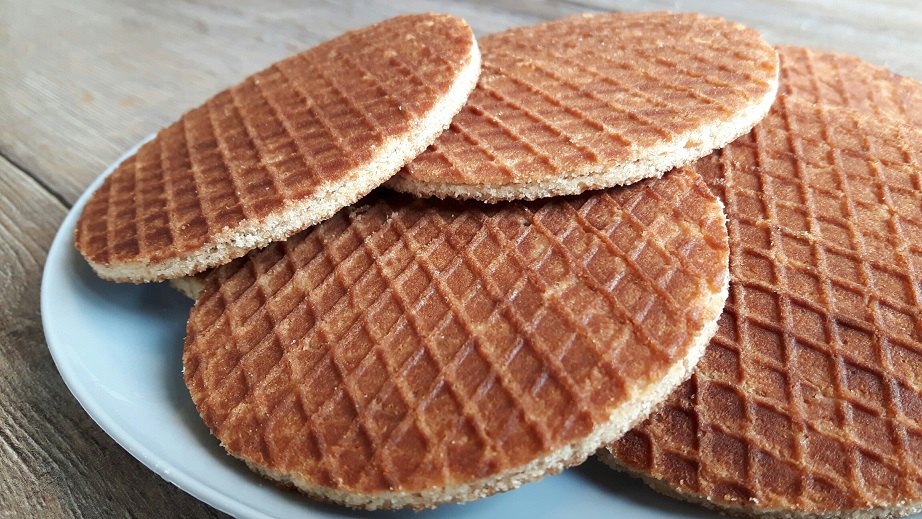
The Dutch delicacy Stroopwafel is a pretty good visual analogy for the
Wafer-Scale Engines
that run inside the two Cerebras CS-3 systems that the Helmut Schmidt University received earlier this year:
Both are made using the largest possible form factor, both are divided into a regular grid, and both deliciously accelerate scientific computing output.
This gives the WSE hundreds of thousands of Processing Elements . In fact, every job on a single CS-3 allocates the full wafer, no matter how many PEs make up the actual program rectangle.
Let’s compare the CS-3 to other parallel systems:
| System | Available cores | Details |
|---|---|---|
| CS-3 | 883350 | Usable program rectangle of 755$\times$1170 PEs (without halo) |
| HSUper | 40968 | 569 nodes $\times$ 72 cores on the largest partition1$^,$2 |
| GPU | few tens of thousands3 | CUDA cores are simpler than CPU cores and non-independent/coupled through SIMT . |
However, leveraging this massive parallel processor for HPC is not trivial, since the program must be written in Python and the Cerebras Software Language 4. (Another main focus of the CS-3 is training ML models, but this topic is not covered in this article.) To expedite the productive use of this hardware, I have put together a simple boilerplate project as an addition to the official SDK examples on GitHub, which can also be used with the Simulator on HSUper. The example illustrates using the WSE for an embarrasingly parallel problem and using the standard library for collective communication across the PEs .
Before we begin, let’s make sure that you can work with the Cerebras simulator or device.
To use the simulator
make an interactive HSUper allocation and run ml python cerebras module.
(For working on another system, such as your own laptop, install the Cerebras SDK.)
To use the device
connect to a Cerebras login node over
SSH
as described here.
Then install uv for running Python scripts.
(This ensures installation of the required Python packages, cerebras-appliance and cerebras-sdk version 2.10.0, is handled automatically.)
Download the example (Note: This can only be accessed through the HSU network or the VPN.):git clone https://git.hpc.hsu-hh.de/rubenhorn/hello-cerebras
The code in the example repository performs are simple map-style operation where for each
PE
,
we compute
$y = i_{\text{PE}} + b$ with the global id of the
PE
$i_{\text{PE}} \in I$ where
$I$ = {$y \cdot \text{width} + x$ | $(x,y) \in [0,\text{width}-1] \times [0,\text{height}-1]$}.
For such embarrassingly parallel workloads, using the
WSE
is as straight forward as using a
GPU
.
The steps involved are illustrated in the diagram below:
This trivial example is just meant as an easy to understand example of the components of a Cerebras
HPC
code.
However, all the discussed components may be used to achieve some actually interesting computation, such as a gravitational $N$-body simulation5:
Broadcasting the position of planets along the x- and y-axis of the program rectangle results in each
PE
computing a single pairwise force contribution. X-axis reduction by summation and integration can likewise be performed using high-level collective operations from the collectives_2d-library.
Compile and run the example using:
| |
With that, let’s look at the technical parts of the example.
Copying memory to and from the device and calling device functions require the corresponding
SDK
object.
To simplify these operations and to allow seamless use of the same scripts on both the simulator and the device, I wrote the simple_wse.py module containing wrapper code around the Cerebras
SDK
.
This module is included with the example project and the script run.py uses it as described below.
All subsequent information thus relates to this helper code and does not necessarily match the underlying usage in the Cerebras
SDK
one-to-one.
The main class is the CerebrasWrapper which is used as a context manager to interact with the simulator or allocate the device in appliance mode:
| |
Data is transferred to the simulator/device in the form of three dimensional NumPy-arrays where the first two dimensions match the corresponding row and column of the program rectangle PE . As described above, a single scalar is copied to a single PE in the example:
| |
| |
| |
The compilation script compile.py likely does not need to be changed for compiling other codes.
Parameterization of the programming rectangle and the single
PE
kernel code are done using get_PE_rect(use_simulator) and get_params(use_simulator) from params.py, respectively.
For example, to add a compile-time scaling factor
alpha, add the following lines:
| File | Contents | ||
|---|---|---|---|
params.py |
| ||
layout.csl |
| ||
pe_program.csl |
|
The role of the other two files is explained in the following section.
Cerebras device code is divided into two parts: layout and PE code.
| File | Contents | Role |
|---|---|---|
layout.csl | Layout code | Map PE code to the program rectangle |
pe_program.csl | PE code | Per- PE kernel code |
The layout is used to define the programming rectangle, perform global compile time calculations/checks, export variable/function names to the host, and map kernel code and parameters to the individual PEs :
| |
x and y as parameters into the kernel but look them up in pe_program.csl using the <layout>-library instead.In the PE code, the variables and functions are exported to match the names exported in the layout code. Note that pointers to the arrays holding the actual data are exported:
| |
In addition to conventional, synchronous functions, tasks are used to perform computation as a response to communication across the fabric, asynchronously. The tasks comprising the example are shown below:
| |
exit-task is essential to guarantee that the kernel completes cleanly.The task code is linked to one of 23 task-ids (8-30) as so:
| |
The 2d-collective communication uses Cerebras concepts such as colors and Data Structure Descriptors 6, to communicate data across the PEs , the details of which are outside of the scope of this article.
Broadcasting values along one axis requires two of the 24 routable colors and its two local task-ids must not collide with those used for the other tasks. The corresponding parameters are created in the layout code:
| |
These parameters are used for importing the module in the PE code, which allocates two out of the eight queues:
| |
Beyond efficient training of ML models, the CS-3 systems provide extremely parallel resources for general purpose computing. For map-and-reduce-like workloads, the provided example can be applied to speed up data processing tasks, where the programming model mirrors that of a GPU . Asynchronous, color-based communication between neighboring PEs and DSDs unlock the potential for more advanced computations, but also increases the programming complexity.
www.techpowerup.com, “GPU Database – NVIDIA L40S”, https://www.techpowerup.com/gpu-specs/l40s.c4173, n.d., (accessed Nov. 06, 2026). ↩︎
Cerebras, “Cerebras SDK – Core Language”, https://sdk.cerebras.ai/csl/language, n.d., (accessed Nov. 06, 2026). ↩︎
In the interest of brevity, this is left as an excercise for the reader. ↩︎
Cerebras, “Cerebras SDK – Data & Execution”, https://sdk.cerebras.ai/csl/language/dsds, n.d., (accessed Nov. 06, 2026). ↩︎